ラベル 2016年の論文 の投稿を表示しています。 すべての投稿を表示

2017年11月27日月曜日

論文読み 2015, 2016, DeepLab v1/v2

元ネタ:
Liang-Chieh Chen and George Papandreou and Iasonas Kokkinos and Kevin Murphy and Alan L Yuille, Semantic Image Segmentation with Deep Convolutional Nets and Fully Connected CRFs, ICLR, 2015.

Liang-Chieh Chen, George Papandreou, Iasonas Kokkinos, Kevin Murphy, Alan L. Yuille, DeepLab: Semantic Image Segmentation with Deep Convolutional Nets, Atrous Convolution, and Fully Connected CRFs, arXiv preprint, 2016

“DeepLab”の初出とその直後に出た論文. 最新のDeepLabv3は現在のstate-of-the-artである.

DeepLabの特徴を3つ挙げる.
1. poolingによるdownsamplingのかわりにAtrous Convolution(fig.1)を使って,downsamplingのときに得られる一つ一つの特徴量がより広い範囲の入力元を反映することになる.Atrous ConvolutionはDilated Convolutionとも呼ばれる. PyTorchではtorch.nn.Conv2dのdilation引数で設定できる.
enter image description here figure 1. from vdumoulin/conv_arithmetic
2. 画面いっぱいに写っていようと画面の片隅に写っていようと猫は猫であるように,image segmentationではscale invarianceを考慮しなければならない. 著者はAtrous Convolutionのdilationを様々に設定することでこれに対処している(fig.2). 著者はこの技法を”atrous spatial pyramid pooling”(ASPP)と呼んでいる.
enter image description here
figure 2, from Liang-Chieh et al. 2016
3. bilinaer upsamplingによってfeature mapを引き伸ばすのだが,その直後にfully-connected Conditional Random Field (CRF)を用いる. CRFはdeep-learning以前のimage segmentationでよく用いられてきた技法である.画像の隣り合った画素のペアを考えて,その2つが同じobjectに入るか否かを計算していくのがUnary(Basic) CRFである(fig.3a). Fully Connecetd CRFでは文字通りある画素とその他の任意の画素のペアが同じobjectに入るか否かを考慮する(fig.3b). 当然Fully Connected CRFはそのままだと極めて計算量が大きいが,Krahenbuhl and Koltun, 2011.は平均場近似を導入して高速化を行い,exhaustiveな計算に近い結果を得た(fig.4).

enter image description here
figure 3. from https://www.cs.auckland.ac.nz/courses/compsci708s1c/lectures/glect-html/topic4c708fsc.htm
enter image description here
figure 4, from Krahenbuhl and Koltun, 2011
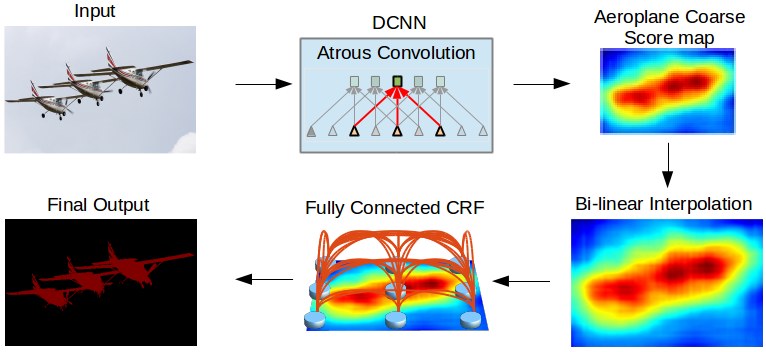

モデル概観, from Liang-Chieh et al. 2015

似たアーキテクチャで注目されているのにZheng et al. Conditional Random Fields as Recurrent Neural Networksがある.

(詳しい議論はDeepLabv3の論文読みで)

2017年11月22日水曜日

論文読み 2015, Rethinking the Inception Architecture for Computer Vision

元ネタ: Szegedy, Christian & Vanhoucke, Vincent & Ioffe, Sergey & Shlens, Jon & Wojna, ZB. (2015). Rethinking the Inception Architecture for Computer Vision. . 10.1109/CVPR.2016.308.

Introduction

Inception1を改良して,Inception-v2並びにv3を開発した.

Inception-v3はInception-v2のAuxiliary classifierにbatch-normalizationを追加したモデルと言える.

General Design Principles

Inception2の改良を試みた際に得たいくつかの経験則を挙げている.
1. layerを急に狭める(representational bottleneck)ことを避ける. ネットワークを通して結局は同じ次元に落とし込むにしても,あるlayerの次のlayerに移る時に急に次元がさげてはならない.
2. 高次元のlayerは局所的に処理しやすい. convoluationにおいてtileごとのactivationを増加させると,抽出される特徴がよりdisentangledになる.
3. 低次元な埋め込みによって,空間的なaggregationをほとんどあるいは全くロスなくおこなえる.例えば(3x3)のconvolutionを行う前に1x1のconvolutionでそのlayerへの入力を低次元に埋め込み,より効率的に3x3のconvolutionを行えて,かつ情報のロスはわずかである.
4. ネットワークの幅と深さのバランスをとる. 片方を増加させることでNNの性能を向上させることは可能だが,療法を同時に増加させることで計算量の増大を抑えつつ性能を向上させられる.

Factorizing Convolutions with Larger Filter Size

Inception3では1x1のconvolutionで次元削減した上で5x5や3x3のconvolutionを行ったが,他のfactorizing convolutionを試している.

3.1 Factorization into smaller convolutions

5x5 や 7x7のconvolutionは非常に計算のコストが大きいので,より小さいconvolutionを複数重ねることで似たようなconvolutionを実現する.(fig.1)
enter image description here

3.2 Spatial Factorization into Asymmetric Convolutions

nxnのconvolutionを1xnとnx1のconvolutionの2段構えで処理する(fig.2)と計算効率は飛躍的に向上する.実験では,lower layers(inputに近いlayer)でこれを行うとうまく行かないが,12x12や20x20のconvolutionでは非常に効果的であった.

4. Utility of Auxiliary Classifiers

Inception4で複数のclassifierを導入して勾配消失を防ごうとしたが,Lee et al[^2]と対照的に著者は複数のclassifierによる収束の高速化は確認できなかった一方で,classifierが一つであるよりも僅かに分類性能の向上を認めた.著者らは複数のclassifierがregularizerとして働いているのではないかと考えている.

5. Efficient Grid Size Reduction

fig.2の方法でfeature mapを効率的に増やしているらしい
enter image description here
figure 2

7. Model Regularization via Label Smoothing (LSR)

training setにおけるラベルの分布を,example とは関係なく得る(traing setにおけるの出現確率かと思ったがそうでもないらしい),またsmoothing parameter を定義する. ground truth のexample に対して,ground truthの分布:(ディラックのデルタ)を,
によって書き換える.
例えばとすれば

である.


  1. Christian Szegedy, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott Reed, Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, Andrew Rabinovich, Going Deeper with Convolutions, In CVPR, 2014 ↩
  2. Christian Szegedy, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott Reed, Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, Andrew Rabinovich, Going Deeper with Convolutions, In CVPR, 2014 ↩
  3. Christian Szegedy, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott Reed, Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, Andrew Rabinovich, Going Deeper with Convolutions, In CVPR, 2014 ↩
  4. Christian Szegedy, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott Reed, Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, Andrew Rabinovich, Going Deeper with Convolutions, In CVPR, 2014 ↩